Adding Other Data Types
Overview
Metadata [1] for a new data types can be added to COPO by following the data
structure described in the
PowerPoint presentation.
The presentation provides a visual representation of the data structure and
the relationships between the different components of data.
The metadata is then presented in a manifest [2] which is also known as a spreadsheet or checklist [3].
Worksheets |
Description |
|---|---|
data |
This worksheet contains the fields for the new data type. It is the main worksheet that defines the structure of the data. See the Mandatory columns in data worksheet tab for the
main columns that should be included in the |
allowed_values |
This contains the possible values for a field and is used to
validate the values entered for the field in the |
checklists |
This worksheet contains the key (i.e. the identifier), name and description of the checklist for the new data type. |
components |
This worksheet lists the name and label of each component
used in the The submission repository is also configured in this worksheet.
It identifies the repository where the data will be submitted to
and is represented as |
Data fields |
Description |
|---|---|
component_name |
The name of the worksheet that the field belongs to. It is used to group related fields together. |
namespace_prefix |
This reflects an established standard that the field belongs to
and matches any of the values in the If the field does not belong to any established standard,
it should have the value |
term_name |
The name of the field. |
term_label |
The label of the field. |
identifier |
This uniquely identifies fields within a component. |
referenced_component |
This refers to the name of the worksheet that the field is associated with. It defines relationships between fields within the same component or across different components. |
term_description |
This provides additional information about the field. |
term_example |
This provides an example and guidance on the expected format of the field. |
term_regex |
A regular expression that is used to validate the data entered for the field. |
term_error_message |
This is used to provide feedback to the user when the data entered for the field does not match an expected outcome. |
term_cardinality |
This defines the number of values that can be entered for the
field. It expects a single value ( |
term_type |
This describes the type of data that the field expects. It can be a string, enum (which stands for enumeration) or file. If it is an enumeration, the possible values for the field should
be defined in the If it is a file, the system will expect a file to be uploaded. |
term_reference |
A URL link referencing a field. It is used to provide additional information about the origin of the field. |
Examples of Adding Other Types of Data in COPO
Tip
Each link below takes you to the corresponding GitHub directory containing the spreadsheet files for that data type. Select a link to view the files and see how the data is structured.
The spreadsheet file containing the main schema can be identified by the
substring _schema_main_.

Extending existing checklist data
Choose one of the data configuration of the existing checklist [3] options in the Examples of Adding Other Types of Data in COPO section above that corresponds well to your new checklist data type and download the spreadsheet file for it before proceeding with either of the subsequent sections:
OR
With a new checklist type
-
Open the spreadsheet and navigate to the
standardsworksheet.Fill in the details of the new standard [4] of your new data type under the columns - key and name.
For example, if you are using the Single-cell main schema spreadsheet to add a new data type, add a row with the following values:
key: ndt
name: New Data Type (NDT)
Note
The key column represents the abbreviation of your new data type while the name column represents the full name of it.
You can choose any abbreviation and name that is relevant to your new data type.

Adding a standard in
standardsworksheet

-
Navigate to the
technologiesworksheet.If your new data type will be associated with a technology that is different to what is displayed in the worksheet, fill in the key and name of the new technology in a new row under the respective columns. Otherwise, skip this step.
Note
If providing a new technology, the key column represents the abbreviation of it while the name column represents the full name of it.

Single-cell shown as the only available technology option in the
technologiesworksheet

-
Navigate to the
checklistsworksheetIn a new row, fill in the details of your new checklist option under the columns - key, name, description, standard and technology.
The standard and technology columns should match the values that you have added in the
standardsandtechnologiesworksheets respectively.For example, in the screenshot below, “My new data type metadata” is a Single-cell option that has been added where:
-
key: version_ndt_sc_rnaseq
Note
The key must begin with the prefix
version_and end with the suffix_sc_rnaseqto indicate that it relates to Single-cell RNA sequencing data.The middle part of the key (
ndt) should represent an abbreviation of the new data type and match the key (i.e. namespace) that was added in thestandardsworksheet.Similarly, the suffix of the key should match a key in in the
technologiesworksheet relevant to your new data type. In this example, it is_sc_rnaseqwhich represents Single-cell RNA Sequencing. name: My new data type metadata
description: This is a new data type.

Adding details of the new data type in the
checklistsworksheet -
-
In the
dataworksheet,-
Insert a column to the far right of the existing columns in the worksheet with the name
version_ndt_sc_rnaseq. This column name should match the key that you added in thechecklistsworksheet.Tip
Alternatively, you can copy and paste an existing column (e.g.
version_mixs_sc_rnaseq) and rename it toversion_ndt_sc_rnaseqif it best suits your new data type. This will ensure that the new column has the same mandatory and optional fields as the existing column’s. You can then modify the values in the new column to suit your new data type.Notice that the adjacent column names also have the prefix
version_and suffix_sc_rnaseqwhich indicates that they are also related to Single-cell RNA Sequencing data but with different data types (e.g. DwC, MIxS, FAANG, ToL).
Adding a data type column in the
dataworksheet -
Existing terms:
Of the existing terms [5] in the
term_namecolumn in the worksheet, insertM(which means mandatory) orO(which means optional) relevant to your new data type in the new columnversion_ndt_sc_rnaseq.If a term is not relevant to your new data type, leave the cell blank.
All terms have a description in the
term_descriptioncolumn. You can use this description to determine whether a term is relevant to your new data type.All terms that have
eiin thenamespace_prefixcolumn are regarded as custom fields that should be marked as mandatory (M) or optional (O) depending on the checklist type in the new`version_xxcolumn.-
Terms that have other namespace prefixes in the
namespace_prefixcolumn likedwc,dcterms,mixs,faang,tol, andschema.orgcan be optional or mandatory for your new data type and as such should be marked asOorMaccordingly or left blank if irrelevant.

Adding existing fields to the new data type column in the
dataworksheet
-
New terms:
If your new data type requires fields that are not present in the
term_namecolumn of thedataworksheet, identify the component in thecomponent_namecolumn to which the new field belongs. Then, insert a new row immediately after the last existing term for that component.Thereafter, fill in the details for each new field you add in the corresponding columns.

Adding new fields for the new data type column in the
dataworksheetThe screenshot above shows two ways of adding new fields to the new data type
version_ndt_sc_rnaseq. It is outlined in red boxes and described below:-
Adding new metadata under a new component: The new metadata is added under a new component called
new_example_component. The new fields are added in new rows immediately after the last existing term of a component.In this case, the last existing term for the
analysis_derived_datacomponent isother_derived_cell_attributes. The new component,new_example_component, is added in a new row immediately after it.
This new component has four new fields - field_1, field_2, field_3 and field_4 with their respective details filled in the corresponding columns and the study_id field as the identifier field.
-
Adding new metadata under an existing component: New metadata is added in new rows immediately after the last existing term for the under the existing component,
sequencing.In this example, field_0 and field_1 are the new fields that are added under the
sequencingcomponent.
-
-
Save the spreadsheet file, commit it and push it to the COPO-schemas GitHub repository.
Follow the steps in the Update schema file version (optional) section to update the schema file version (optional).
Proceed to the Persist added data to COPO section for the next steps.


With additional fields for an existing checklist type
Open the spreadsheet and navigate to the
dataworksheet.-
Choose any of the existing checklist types in the worksheet that is relevant to your new data type. They are identified with the prefix
version_in the column names.We’ll choose
version_mixs_sc_rnaseqandversion_faang_sc_rnaseqin this example proceed with the next steps.
Red rectangle highlighting the existing checklist types in the
dataworksheet
-
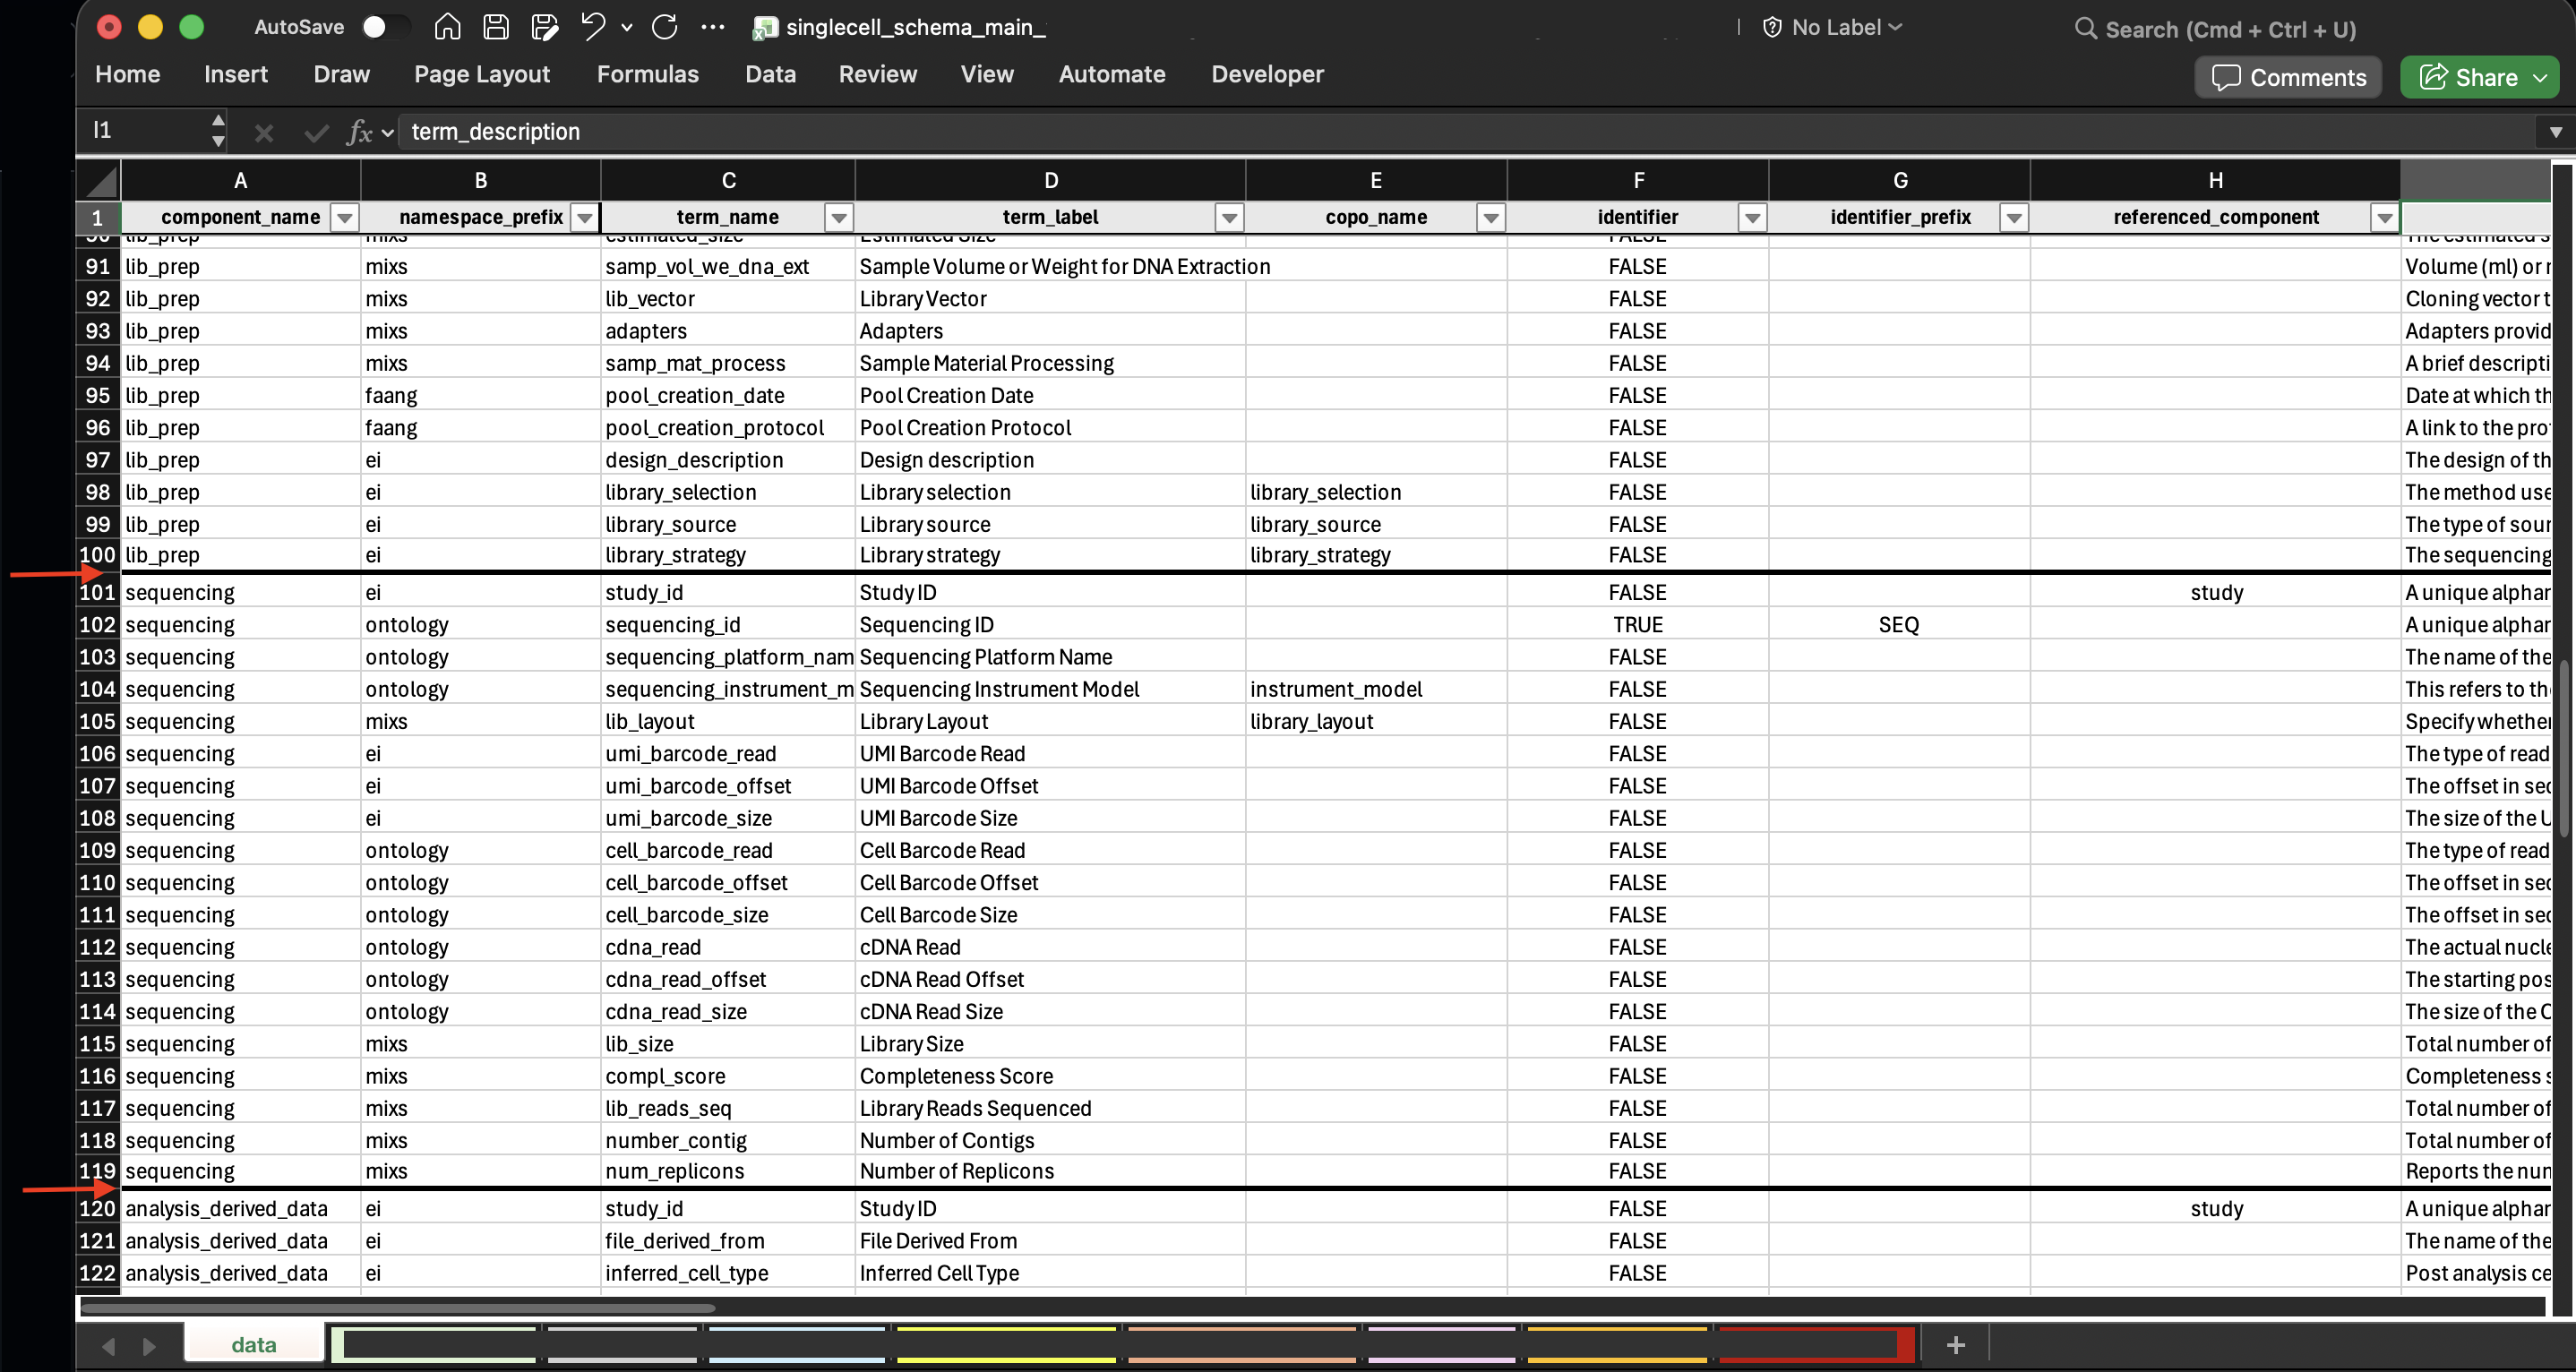
Choose a component in the
component_namecolumn to which the new fields will belong to. Then, insert new rows immediately after the last existing term for that component.In this example, we will add new fields under the existing components -
lib_prep- The last existing term for this component islibrary_strategy. We will insert a new row immediately after it.sequencing- The last existing term for this component isnum_replicons. We will insert a new row immediately after it.

Red arrow highlighting where new field data will be inserted in the
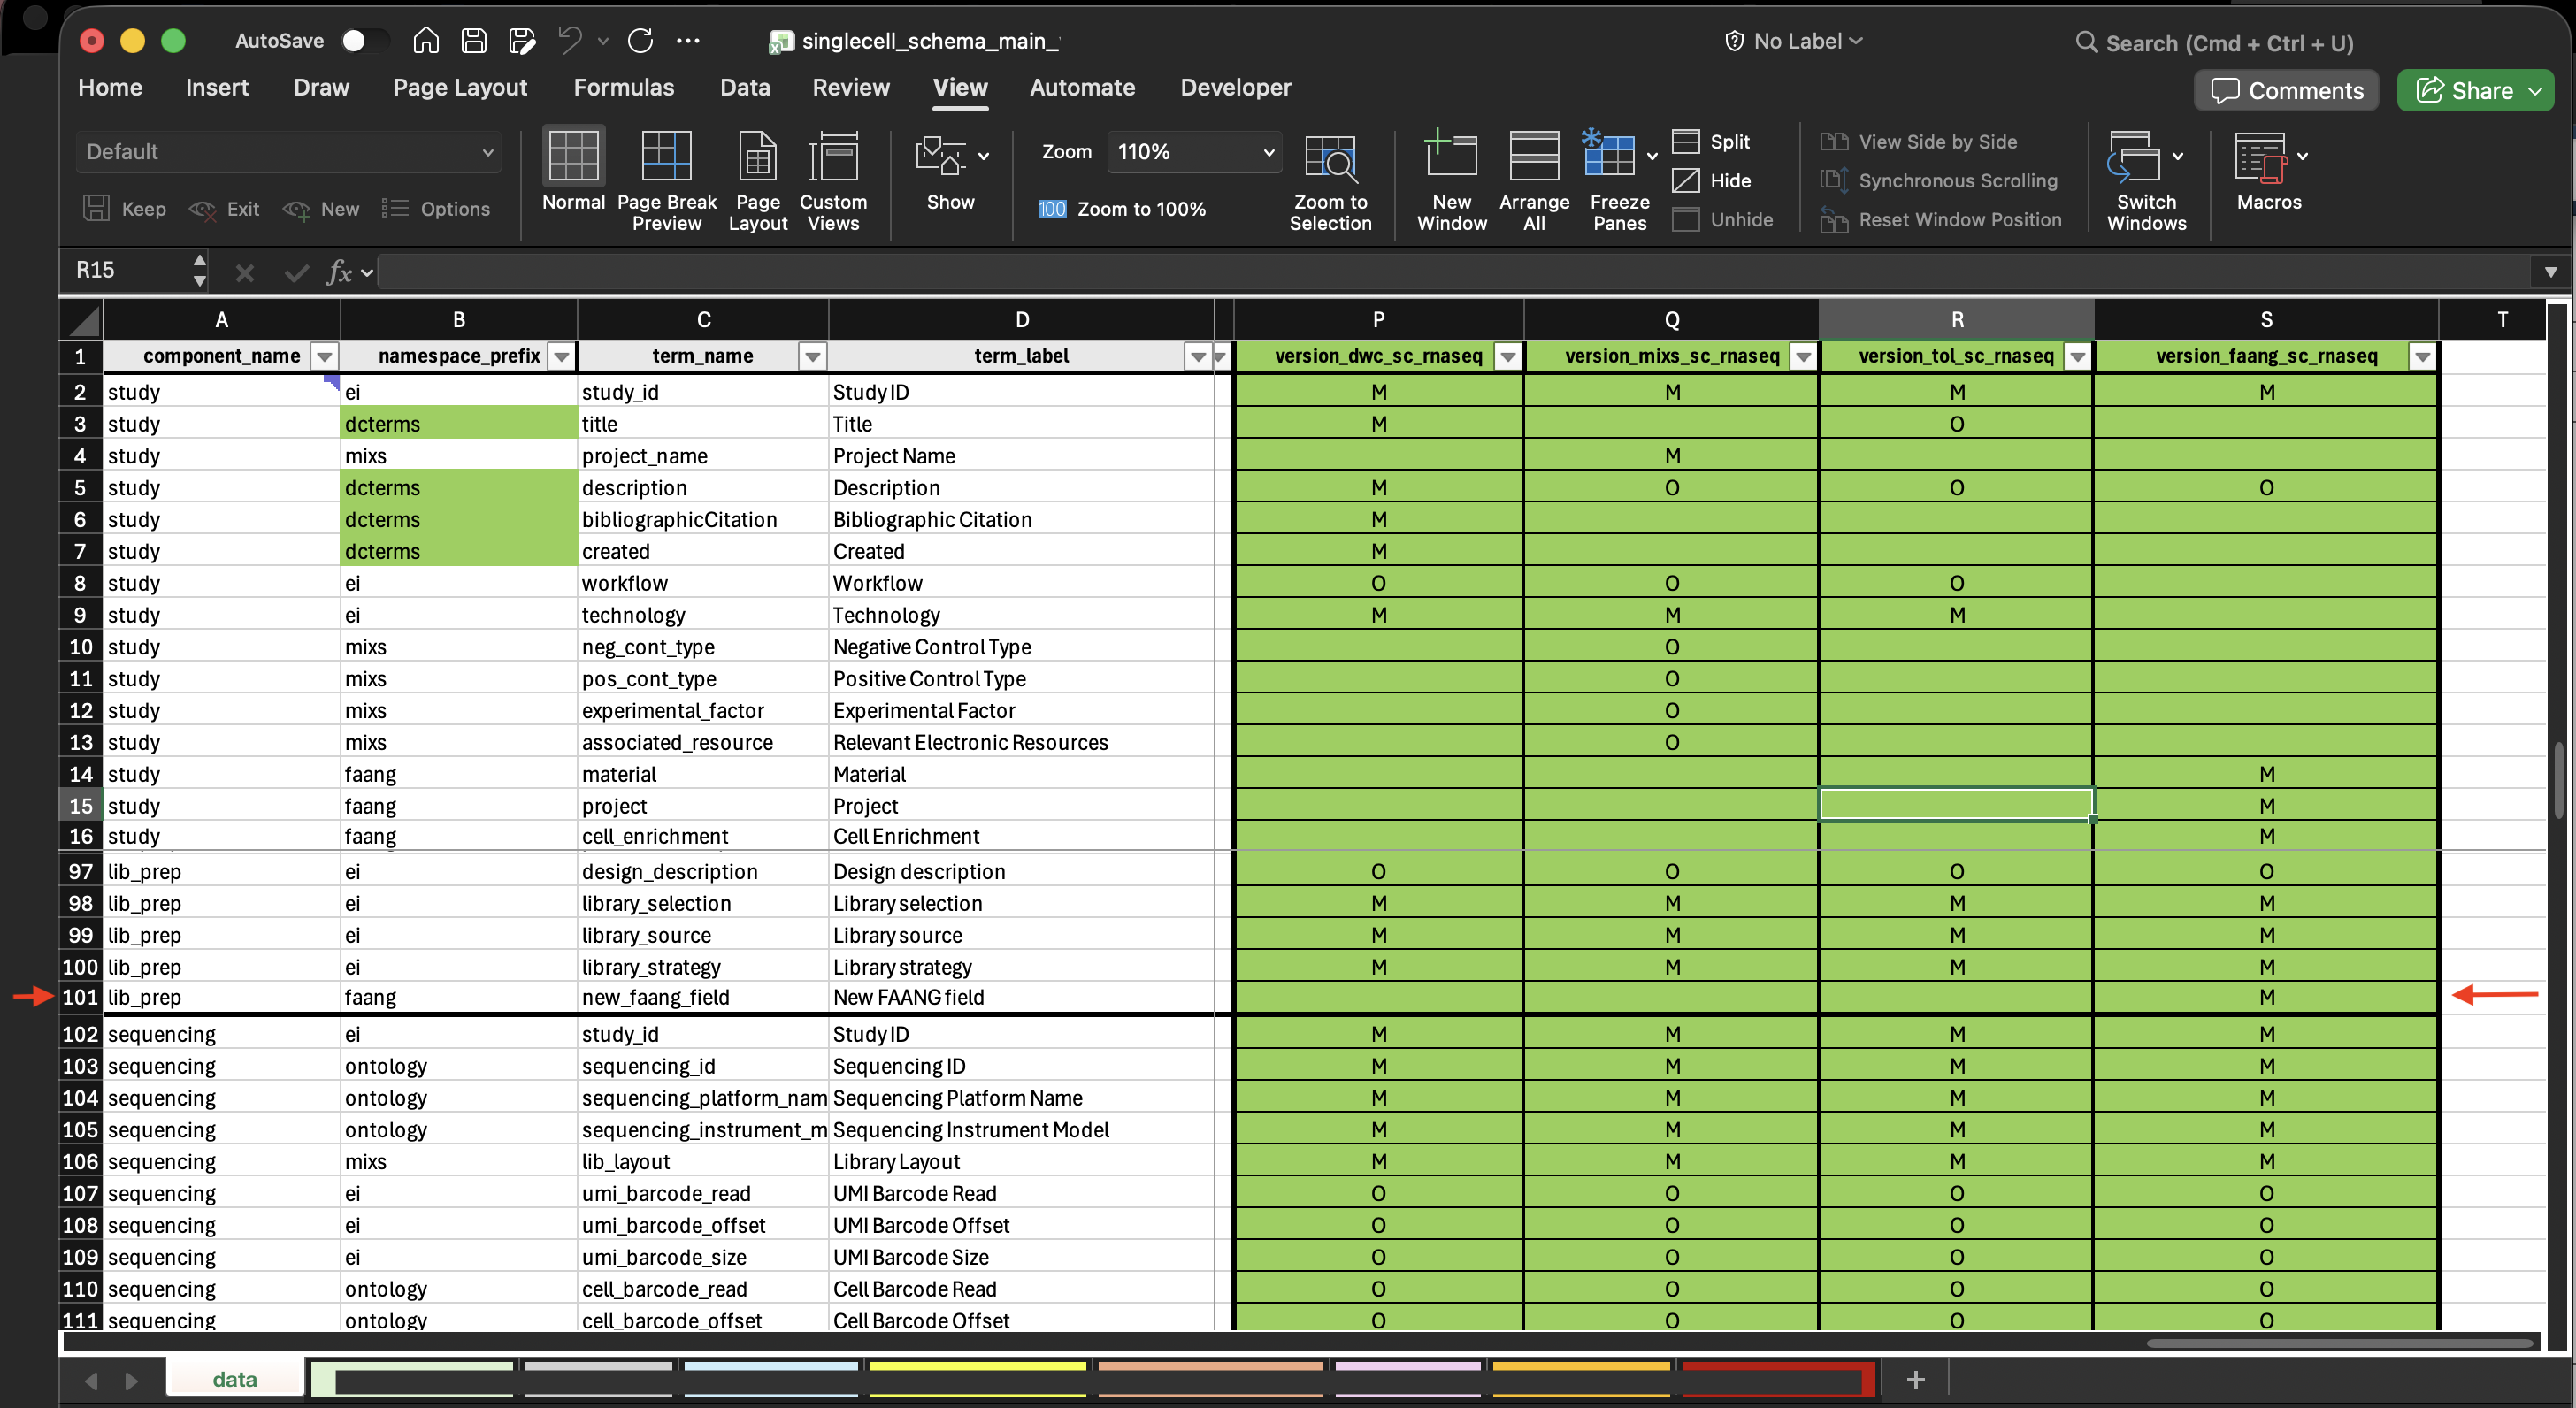
dataworksheetIn the screenshot below, notice that the inserted row in the
lib_prepcomponent hasMin theversion_faang_sc_rnaseqcolumn and nothing in the other version_xx columns. This indicates that the inserted field (also known as term) is mandatory for the Functional Annotation of Animal Genomes metadata (FAANG) checklist type and not relevant to the other checklist types.Note
Fields that belong to an established standard in the
dataworksheet must have any of the standards listed in thekeycolumn of thestandardsworksheet as a value in thenamespace_prefixcolumn of thedataworksheet.Custom fields must have
eias the namespace prefix in thenamespace_prefixcolumn of thedataworksheet. These fields can be marked asMorOin the version_xx columns, depending on whether they are mandatory or optional for your new data type.
Red arrow highlighting inserted data in
lib_prepcomponent in thedataworksheetSimilarly, the inserted row in the
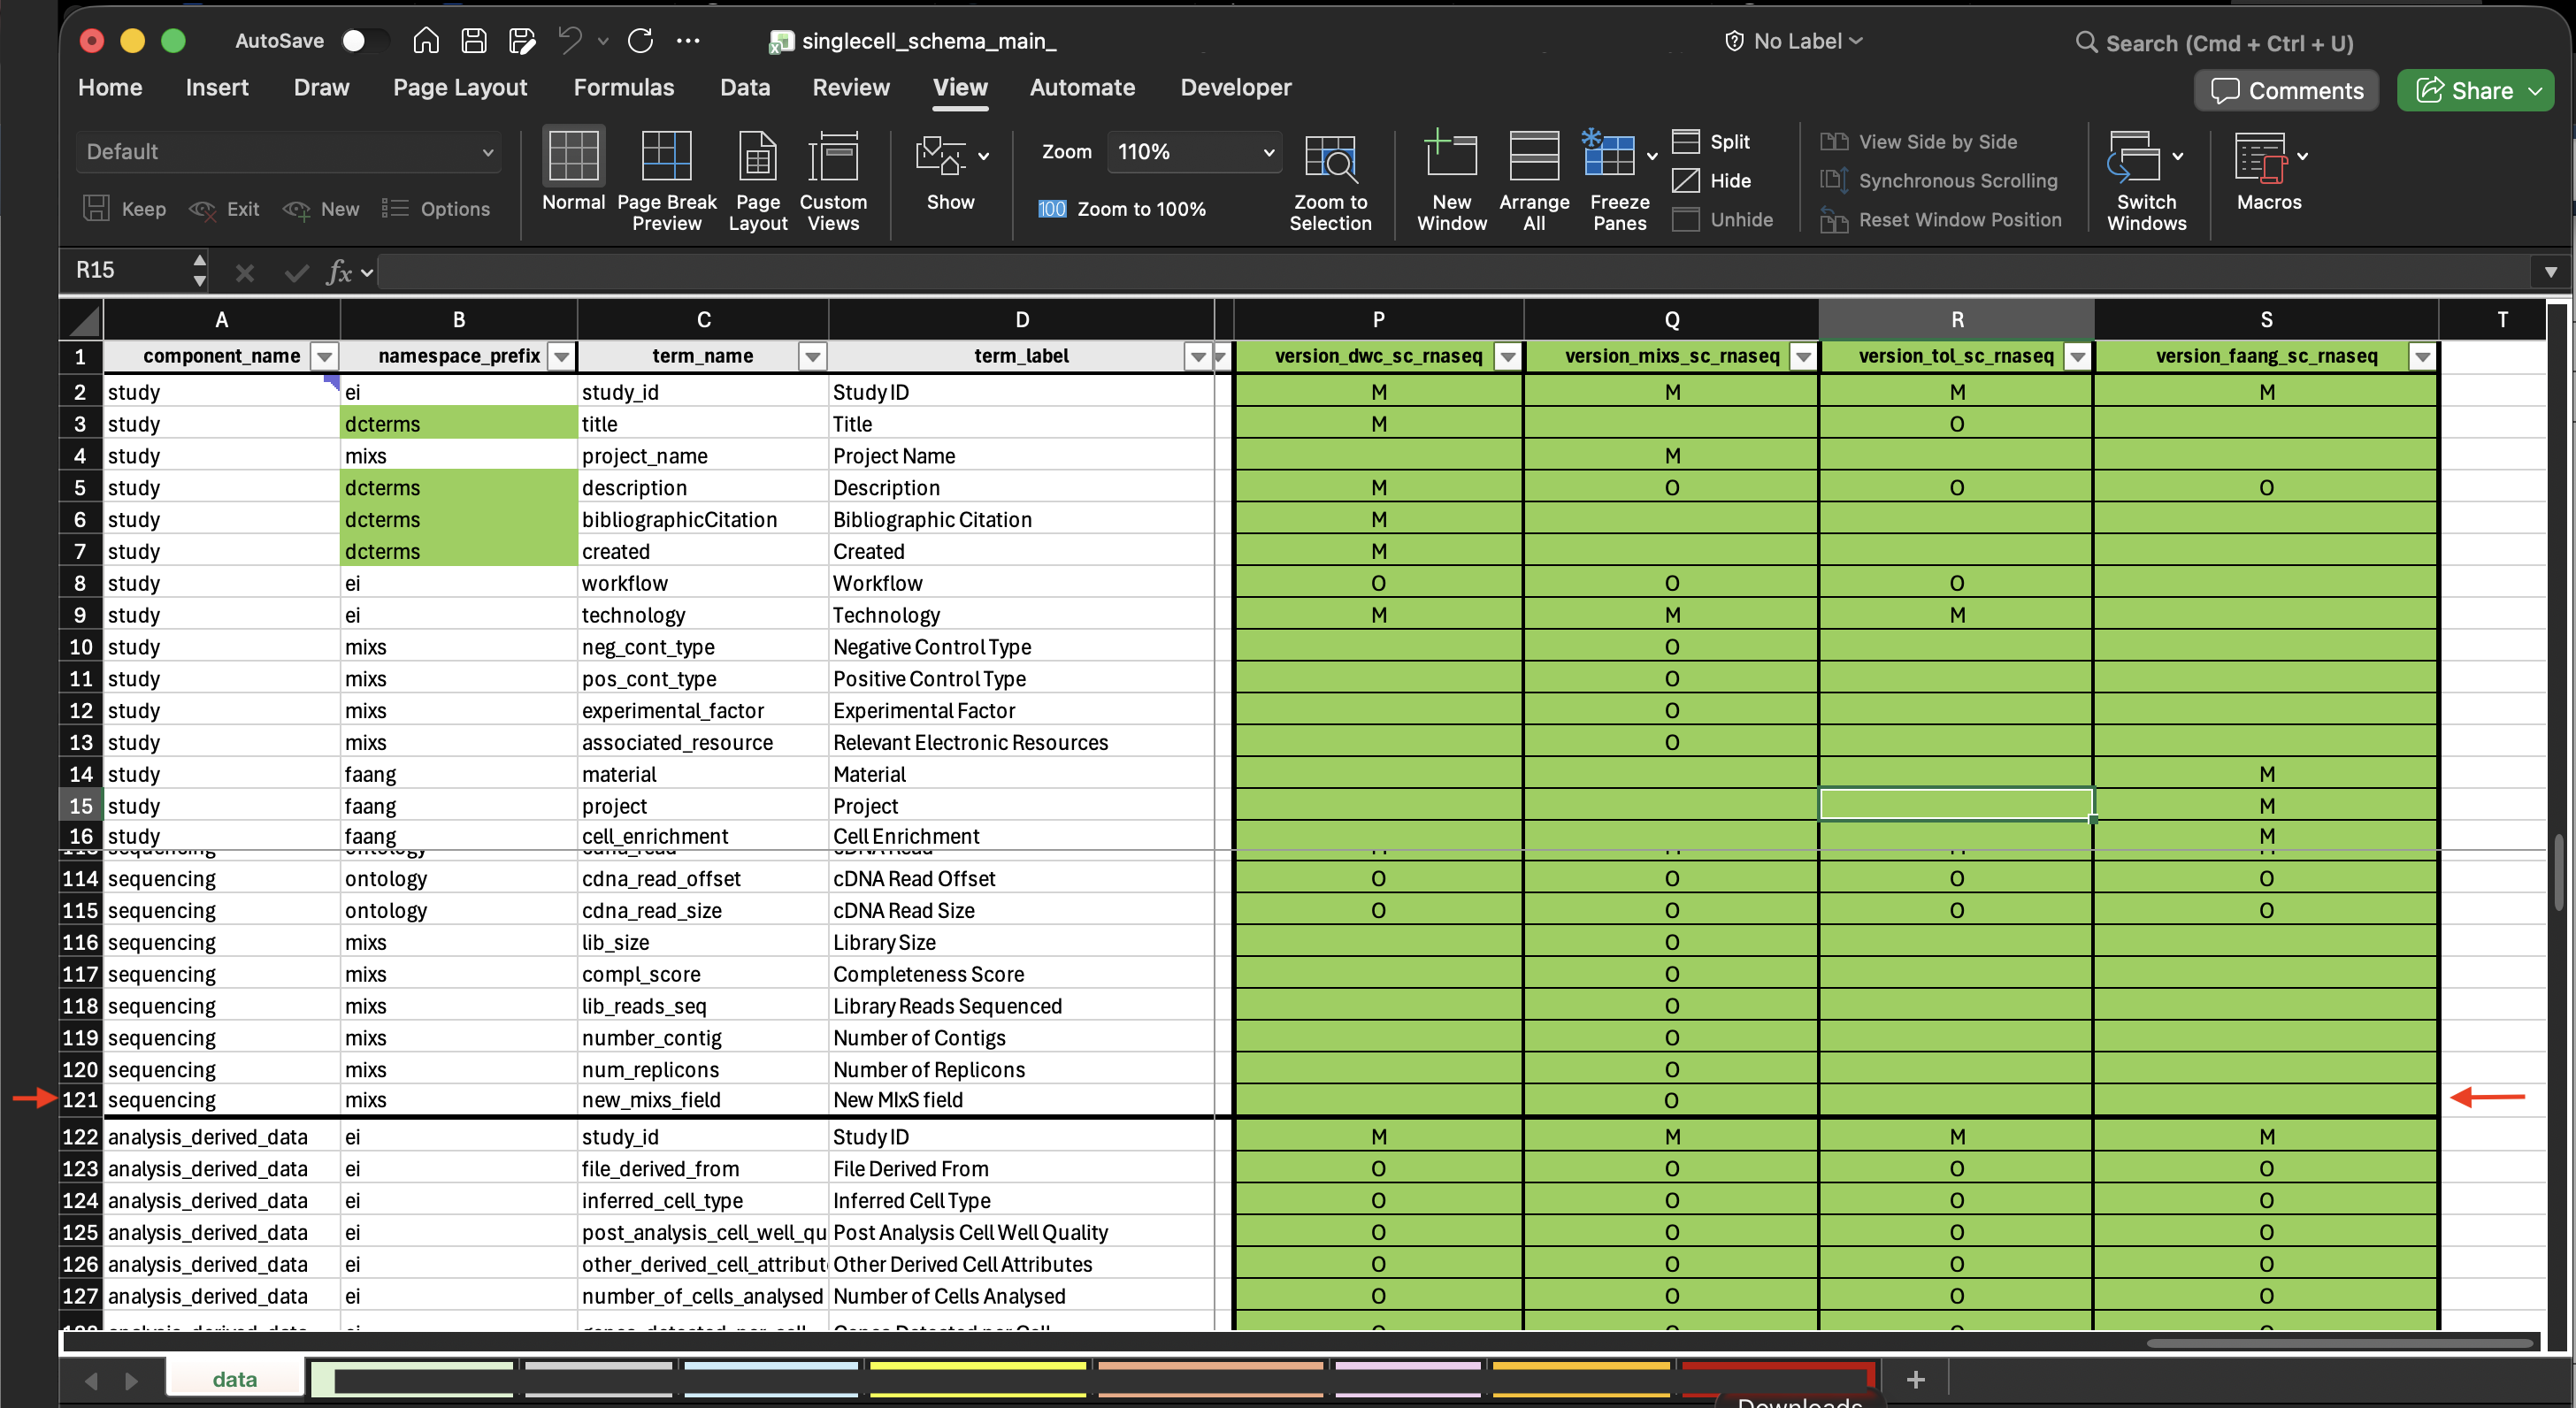
sequencingcomponent hasOin theversion_mixs_sc_rnaseqcolumn and nothing in the other version_xx columns. This indicates that the inserted field is optional for the Minimum Information about any (x) Sequence (MIxS) checklist type and not relevant to the other checklist types.
Red arrow highlighting inserted data in
sequencingcomponent in thedataworksheet
Save the spreadsheet file, commit it and push it to the COPO-schemas GitHub repository.
Follow the steps in the Update schema file version (optional) section to update the schema file version (optional).
Proceed to the Persist added data to COPO section for the next steps.

Update schema file version (optional)
If you’ve made significant changes to the data structure of a main schema
spreadsheet file, it is recommended to increment the existing version number
to reflect the changes made or add the path of the new schema file to the
COPO_SCHEMA_URL list in the data.py file
located in the src/main_config/settings directory of the project of the
COPO-production GitHub repository.
Important
The key (which is the schema name) in the MANIFEST_VERSION dictionary in the data.py file must match the schema name configured for the data type component in the setup_profile_types.py Django command.
...

MANIFEST_VERSION =  {
   "ASG": "2.5",
   "DTOL": "2.5",
   "DTOLENV": "2.4",
   "DTOL_EI": "2.4",
   "ERGA": "2.5.1",
   "DTOL_BARCODE": "",
   # Update the version number of existing schemas
   "COPO_SINGLE_CELL": "0.4",
   "COPO_IMAGE_REMBI": "0.1",
   "COPO_IMAGE_STX_FISH": "0.1",
   "COPO_READ": "0.1",
   "EI_EDP": "0.1",
   # OR...Add schema name and version number for your new data type here
   # "<data-type-schema-name>": "<version-number>",
}

...
...

SINGLE_CELL_SCHEMAS_URL = [
   "COPO_SINGLE_CELL": f"https://github.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/single_cell/singlecell_schema_main_v{MANIFEST_VERSION['COPO_SINGLE_CELL']}.xlsx",
   "COPO_IMAGE_REMBI": f"https://github.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/images/rembi_image_schema_main_v{MANIFEST_VERSION['COPO_IMAGE_REMBI']}.xlsx",
   "COPO_IMAGE_STX_FISH": f"https://github.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/images/stx_fish_image_schema_main_v{MANIFEST_VERSION['COPO_IMAGE_STX_FISH']}.xlsx",
   "COPO_READ": f"https://github.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/reads/reads_schema_main_v{MANIFEST_VERSION['COPO_READ']}.xlsx",
   "EI_EDP": f"https://github.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/edp/edp_schema_main_v{MANIFEST_VERSION['EI_EDP']}.xlsx",
   # Add the path to your spreadsheet file here
   # e.g. "https://raw.githubusercontent.com/EarlhamInst/COPO-schemas/raw/refs/heads/main/<folder-name>/<data-type-name>_schema_main_v{MANIFEST_VERSION['<data-type-schema-name>']}.xlsx"
]

...
Persist added data to COPO
Now that the data structure has been amended and the new data type has been added to the spreadsheet file in the COPO-schemas GitHub repository, the following steps guide how to persist added data type(s) to the COPO website so that they are available as a dropdown menu option and the new data is available within the downloaded spreadsheet file for the respective checklist type.
ssh <name-of-vm>
For a local setup, skip this command and proceed to the next one.
docker ps
You may need to run the command with sudo if you are not logged in as a
user with the required permissions to run Docker commands.
docker exec -it <copo-web-container-id> bash
Replace <copo-web-container-id> with the actual container ID of the
COPO web container found from running the docker ps command.
On the production, demonstration and development virtual machines (VMs),
the COPO web container can be identified by copo/copo-new-web:vxx
where xx is the version of the Docker container image.
On the other hand, locally, the COPO web container can be identified by
local_copo_web:vxx where xx is the version of the Docker container
image.
celery -A src call src.apps.copo_single_cell_submission.tasks.update_singlecell_schema
This command calls the update_singlecell_schema Celery job defined in the src/celery.py file, which in turn calls the update_singlecell_schema Celery task defined in the src/apps/copo_single_cell_submission/tasks.py file.
The updateSchemas function in the src/apps/copo_single_cell_submission/utils/SingleCellSchemasHandler.py file is then called and is responsible for parsing the spreadsheet file from the GitHub repository, updating the system’s database and by extension the website with the new data.
To verify that the new data type has been added, navigate to the Single-cell submission page under a Biodata profile on the COPO platform and check if the new data type is available in the dropdown menu or the new data is available within a downloaded spreadsheet file from the page.